Claude
 Cursor
 Codex
 Hugging Face
 NVIDIA
 Visual Studio Code
 Devin
 Kiro
 Open Code
 NanoClaw

 Docker
 npm
 PyPy
 Wiz

 Financial Services
 Gaming
 Public Sector
 Automotive
 Technology
 Healthcare


Definition
Data-centric AI treats training data and evaluation datasets as an engineered, versioned asset that a team improves across the model lifecycle and re-validates as conditions change. For many production tasks with a reasonable baseline architecture, teams can gain more by correcting dataset defects than by continuing architecture tuning. Those defects also create model risk. Teams can trace errors to records they can fix and audit, improving accuracy while reducing the risk of shipping an unexplained model.
Data-Centric AI: Core Principles
Recent industry research, building on concepts championed by Andrew Ng, defines data-centric AI as a necessary shift in focus, proving that carefully engineering data is essential for AI systems to actually work. The core framing: AI systems = Code + Data, and when an ML model underperforms, improving the data often beats changing the code. Data-centric work holds the model fixed and gains performance by raising data quality and quantity instead.
Iterating on data at scale needs machine learning operations (MLOps) for versioning and lineage.
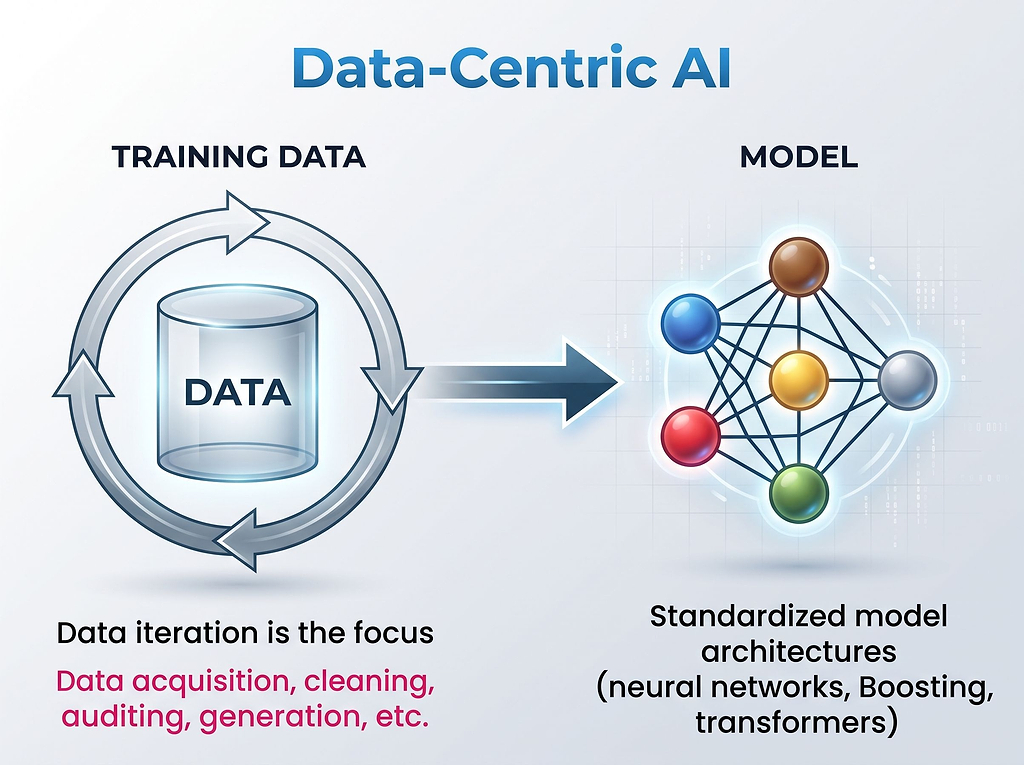
What is Data-Centric vs Model-Centric AI?
Model-centric AI holds the dataset fixed and tunes architecture and hyperparameters; data-centric work holds the model fixed and repairs the data. Tuning cannot resolve label errors or sampling bias. It also cannot refresh stale records.
Annotation noise, mislabeled records, sampling bias, and stale data are structural defects that architecture tuning cannot repair. When labels are wrong, annotation noise sets the accuracy ceiling regardless of model complexity or hyperparameter search. Both approaches run together in practice.
What are the Core Workflows of Data-Centric AI
Collection, labeling, validation, augmentation, and feature engineering repeat across a model’s life.
Data collection and curation
Teams source data that matches production inputs, then filter out low-quality and duplicate records. Filtering removes low-quality records based on explicit quality signals, while deduplication strips near-duplicate examples shared between training and evaluation splits so the test set does not leak into training.
Labeling and annotation
Consistent labels need written guidelines and an agreement threshold between annotators. Teams can use weak supervision where hand labeling does not scale.
Data validation and cleaning
It’s imperative to check for label errors and outliers before training. Data cleaning can meaningfully improve model performance, but teams must validate cleaning decisions against downstream model performance rather than apply them as a blanket pass. Indiscriminate cleaning can remove signal the model needs and degrade results.
Data augmentation and synthetic data
Synthetic and augmented examples cover rare classes and occlusions. They can also represent malformed inputs that the collected data misses and that the training set would otherwise omit. Teams must version synthetic records and label them as synthetic so their share of the training set stays auditable.
Feature engineering
Feature engineering involves shaping raw records into model-ready signals and versioning those transformations alongside the dataset.
What Tools and Platforms are Available for Data-Centric AI?
Several tools address specific data-centric tasks across the ML pipeline.
- Label error detection: Cleanlab applies confident learning to rank records in an existing dataset by the probability that their label is wrong, so reviewers inspect the flagged subset instead of re-auditing the whole set.
- Programmatic labeling: Snorkel replaces hand labels with labeling functions that encode weak supervision rules, letting subject-matter experts define ground truth at scale.
- Visual inspection iteration: LandingLens, from Landing AI, structures the workflow around dataset iteration rather than architecture tuning.
- Pipeline checklists: DC-Check is a published checklist that walks a team through data-centric decisions at each stage of the ML pipeline.
- Dataset versioning and drift monitoring: Dedicated tooling tracks dataset versions over time and alerts teams when production data shifts away from training distributions.
What Makes a Good Training Dataset?
Domain experts and machine learning engineers define a good training dataset as sufficient and representative.
Defined with domain experts
Domain experts define ground truth. In visual defect inspection, inspectors decide what is a defect and what is surface noise.
Sufficient
You need enough examples to learn real patterns and absorb real-world noise, with class balance that matches the problem. In domains where large datasets do not exist, a small but carefully engineered and consistently labeled set can be enough, provided every example is purposeful and the labels are precise.
Representative
An object detector must see difficult cases such as occluded cars and look-alikes. When data drifts, weigh a new training set against retraining costs; the right trigger depends on how fast inputs move.
Data-Centric AI Across Application Domains
Data quality problems take different forms depending on the domain, and so do the interventions that move the needle.
- Computer vision: Annotation noise and near-duplicate contamination between train and test sets set the accuracy ceiling. Object detectors need difficult cases such as occluded and look-alike examples; if teams omit hard negatives from training, the model will fail on them regardless of architecture.
- Natural language processing: Evaluation benchmarks carry more label errors than commonly assumed: sampled error rates of 16.9% on MNBM and 21.2% on BEGIN. Correcting those labels lifted GPT-4’s ROC AUC from 0.81 to 0.93 on affected tasks.
- Tabular data: Missing values and inconsistent schemas dominate; teams must also detect outliers. Validation rules and versioned feature transformations carry most of the gain here.
- Manufacturing inspection: Manufacturing inspectors define what counts as a defect and what counts as surface noise, and defect classes are rare and heavily imbalanced. The interventions that move accuracy are consistent labeling standards, including written guidelines and relabeling disputed images to a single agreed boundary, plus examples of the specific defect types the line produces.
Why Data Quality Drives Model Performance
Accurate labels and representative coverage shape the accuracy ceiling, while bias can further limit performance.
Accuracy and reliability
Mislabeled records limit what a model can learn. In a 2026 study of construction-product records, rigorous cleaning raised test R² from 0.30 to 0.88; hyperparameter tuning afterward added 0.02.
Bias and fairness
Skewed samples and inconsistent labeling encode bias that no hyperparameter change removes. EU AI Act Article 10 requires bias examination and mitigation for high-risk systems.
Reproducibility
Teams must record the exact dataset version with each result for that result to repeat. One concrete mechanism is to pin an immutable dataset version and its complete preprocessing configuration, including split definitions, to each logged experiment run. Researchers can then reproduce any result exactly at a later date.
Cost and speed
Subject-matter experts encode their domain knowledge once as labeling functions, which are short rules or heuristics that vote on each record’s label. Those functions then apply automatically to every unlabeled record in the dataset. The number of labeling functions determines labeling cost regardless of how many records the system processes. When teams refresh the underlying data, re-labeling means re-running the same functions rather than recruiting and briefing a new cohort of annotators.
Data-Centric AI and the AI/ML Software Supply Chain
Datasets and models are supply chain artifacts with the same failure modes as packages.
Datasets and models as governed artifacts
Version every dataset immutably and record lineage to the trained model. Management-system standards and AI regulations converge on the same expectation: an organization must be able to produce a documented record of where each dataset came from and how it changed across the lifecycle.
Data provenance and integrity
Treat provenance as a software provenance problem. Record where each dataset came from and who owns it. Document every transformation separately.
Data poisoning as a supply chain risk
An attacker inserts or modifies training samples so the model learns an attacker-chosen behavior. JFrog Security Research identified roughly 100 malicious models on Hugging Face whose attackers injected the payload into PyTorch model files through the pickle module’s __reduce__ method. On deserialization, the payload opened a reverse shell, giving attackers silent access to any environment that loaded the model. Verify upstream datasets and models before they enter training.
AI bills of materials and software bills of materials as evidence
An AI bill of materials (AIBOM) extends the software bill of materials (SBOM) with model and dataset composition. On May 12, 2026, CISA and G7 partners published SBOM for AI guidance with minimum elements.
Operationalizing Data-Centric AI in Production
Teams run error analysis to find data gaps, then retrain on the fix.
Integrating into MLOps and CI/CD pipelines
Run data validation as a gate in CI/CD for ML, the way unit tests gate code. Log the dataset version with the hyperparameters in experiment tracking.
Dataset versioning and lineage
A provenance graph linking each dataset version to the runs and models derived from it shows which retrainings reached production, so teams can stop paying for retraining that never ships. Register each model in a model registry with a pointer to its immutable dataset version.
Monitoring data drift and retraining
Continuous monitoring involves running statistical drift tests on production inputs. To establish an effective retraining trigger, organizations measure short-term model degradation after a day and a week, and then compare those results against the performance of a quarter-old model.
Data governance and compliance
EU AI Act Annex IV requires datasheets covering training data provenance and labeling procedures. The datasheets must also describe cleaning methods; Article 12 requires automatic event logs.
What are Best Practices for Adopting a Data-Centric Approach?
Teams adopting data-centric AI practices start where relabeling produces a measurable gain. By demonstrating the result on a single use case first, teams can validate the approach before standardizing the workflow across pipelines.
- Pilot first: Pick one use case where relabeling shows a measurable gain.
- Set standards: Define quality bars and validation protocols. Set annotator agreement thresholds separately.
- Version like code: Store datasets and their labels immutably. Document every source and transformation.
- Distrust upstream data: Validate third-party and retrieved data before use.
- Adopt MLOps and DataOps: Run data operations (DataOps) for pipelines alongside MLOps for models.
- Close the loop: Analyze model errors to prioritize the next data fix.
Common Questions About Data-Centric AI
Data-centric machine learning raises questions about scope and workflow, including governance requirements.
What is the 30% rule in AI?
Gartner introduced the 30% rule in a Gartner analyst forecast published in July 2024, predicting that organizations will abandon at least 30% of generative AI projects after proof of concept by the end of 2025. Gartner named poor data quality, inadequate risk controls, escalating costs, and unclear business value as the primary causes. Gartner published this as an analyst forecast without measuring an observed abandonment rate.
What does AI-centric mean?
AI-centric describes an organization or product that places AI at the core of its offering or operating model, making it a strategy-level term. Data-centric and model-centric, by contrast, describe where an engineering team directs its iteration effort: on improving the dataset or on tuning the architecture and hyperparameters. The terms operate at different levels and are not mutually exclusive.
Does data-centric AI still matter for LLMs and foundation models?
Yes. Ablation studies on large-scale pretraining datasets show that models identical in parameters and architecture, with the same token count, scored 33% versus 37% on MMLU and 46% versus 57% on ARC purely because researchers applied quality filtering to the training data. In the same research, the higher-quality dataset reached 33.6% MMLU at 38 billion tokens, while the next-best dataset required roughly 300 billion tokens to reach a comparable score. Data quality remains a primary lever even when researchers hold model architecture constant.
What is data-centric AI?
Data-centric AI treats training data as an engineered, versioned asset and improves its quality and consistency throughout the model lifecycle while preserving provenance.
What is the difference between data-centric and model-centric AI?
Model-centric AI changes architecture and hyperparameters; data-centric AI improves labels and coverage while keeping data fresh and holding the model relatively stable.
How can organizations shift from model-centric to data-centric?
Start with a high-impact pilot, set quality standards, version datasets like code, and use deployed-model errors to prioritize the next fix.
What are the core workflows in data-centric AI?
The continuous workflows are collection and curation, labeling, validation and cleaning, augmentation and synthetic data, and feature engineering.
Why does data quality matter more than model architecture?
Label errors, noise, bias, and stale records constrain accuracy despite tuning. When annotation errors in widely used evaluation benchmarks reached double-digit rates as recently as 2025, partly wrong labels cause evaluators to score even a well-tuned model inaccurately. No amount of architectural refinement overcomes a ceiling set by the data itself.
How does data-centric AI relate to MLOps and the AI supply chain?
It depends on dataset versioning and lineage, plus drift monitoring and CI/CD for ML. Provenance checks guard against poisoning. Ungoverned model pulls become shadow AI.
How Does JFrog Help With Data-Centric AI?
Why JFrog? Datasets and models stay trustworthy when teams maintain version histories and connect scan results to provenance records. The JFrog Software Supply Chain Platform connects Artifactory storage, Xray scanning, Curation controls, and JFrog ML lineage so teams can trace AI artifacts from ingestion through runtime.
- JFrog ML: Records model versions and their dataset lineage while extending artifact governance to AI/ML models.
- JFrog AI Catalog: Discovers AI assets and applies governance and security controls. shadow AI detection helps ensure that only trusted, curated models and datasets reach production.
- JFrog Artifactory: Consolidates Hugging Face and ONNX models in one repository and supports Safetensors. Checksum-based deduplication stores each model binary once regardless of how many repositories reference it.
- JFrog Curation: Blocks risky or malicious open-source packages at ingestion through a Package Traffic Controller, stopping suspect components before they reach a training pipeline.
- JFrog Xray: Performs deep recursive scanning of binaries and all transitive dependencies against a database of 4M+ open-source packages.
Point your model pipeline at Artifactory as its model repository and turn on Xray scanning for that repository. Xray scans artifacts in the repository before the pipeline uses them, while JFrog ML records model versions and their dataset lineage.
To see how this fits your own model pipeline, book a demo or start a free trial of the JFrog Platform to explore the tooling firsthand.